

Quick reference
1
Navigate to the Data Integrator page
In the Console sidebar, navigate to Integrations → File-based.
This page is only visible if you have the
write:integrations_manager
permission.2
Create a new integration
- Integration Name: Name for the integration. Make it unique to this integration.
- Integration Type: Determines the endpoints that will be used to ingest data. It maps directly to the SkillEngine API endpoints.
3
Configure the Input Node
- Click the node to open the detail view.
- There is one
primaryinput set up. Uploading files for this configuration will trigger the integration if enabled. - Set up the other fields for the file or connection.
- Optionally, configure extra sources. Click
Add Source, choose a sensible alias, indicating what the source is about.
4
Join configured inputs
Drag edges from one input down to another on the left side of the input
node. Join arrows can only go downwards. This links inputs together.
5
Configure the Output Node
- Click the node to open the detail view.
- Set the
Delivery Typeto whichever is applicable. - For certain delivery types, choose to
Auto-generate External IDs.
6
Add connections and operations to transform input to output
- Right-click to add operations.
- Connect handles to make the data flow from one operation to another.
- Save your integration.
Setting up an integration
A new integration is defined by a set of data inputs (files, connectors) that together form a datasource to be loaded into the SkillEngine API. An integration can be “recurring”, each new file upload or connector trigger being an updated version of the same source. One of the inputs is theprimary, the driver of the integration. When that
input is triggered with new data (a new file arrives, a connector is triggered),
the integration is considered out of date, and will try to update the
SkillEngine API with the new data.
Example: Learning Skill Event integration
Example: Learning Skill Event integration
An example is a Learning Skill Event integration. At the customer’s side,
there is a learning system, which can export a CSV file with the learner’s
ID, Name, Email, Learning Title, and Learning Description. The
ID does not directly map to an Employee in the SkillEngine API, but we do
have an export from our identity provider that contains that mapping.Together, the learning_events_20260101.csv and
identity_provider_mapping_20260101.csv form a datasource to be loaded
into the SkillEngine API.The learning_events_20260101.csv file is the primary file, and the
identity_provider_mapping_20260101.csv file is an extra file. The
integration will be run on the learning_events_20260101.csv file, and
will use the latest version of the
identity_provider_mapping_<latest_date>.csv file to map the learner’s
ID to an Employee in the SkillEngine API.run is
created for that integration. A run is defined as a single execution of an
attempt to reconcile new or specified input data with the SkillEngine API.
Step 1: Creating a new integration
Integrations are created in the Data Integrator UI, in the Console. Navigate to Integrations → File-based in the sidebar. If you have thewrite:integrations_manager scope on the Console, you will see a
+ Create Integration button.
This will open a modal that first asks more details about what type of
integration you want to create, after which it will drop you in the Integration
Editor.
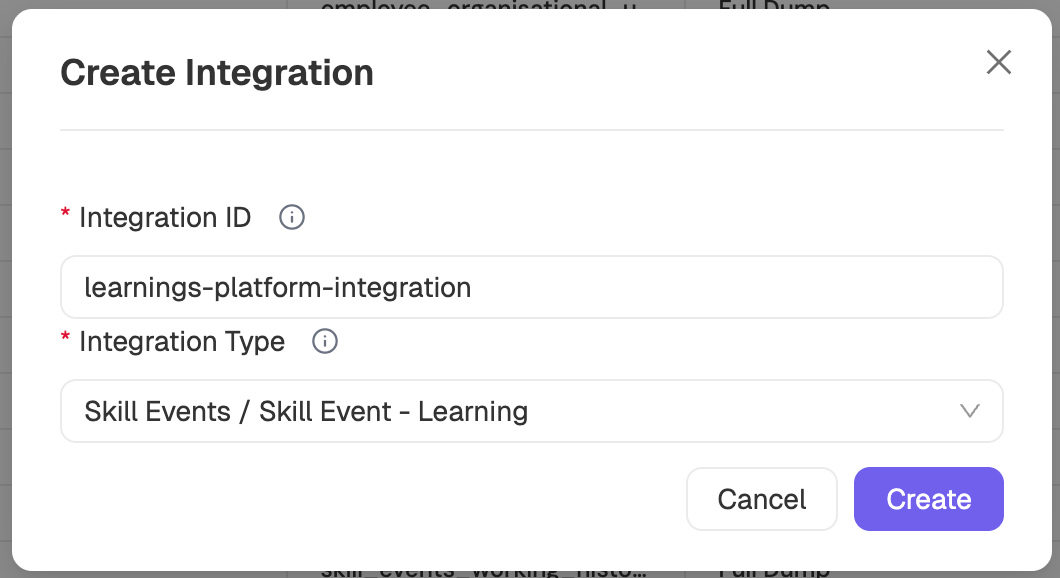
Integration Name, make it unique to this integration. This is used to
identify the integration.
For the Integration Type, select the type of integration you want to create.
These map directly to the SkillEngine API endpoints.
Click Create to navigate to the integration editor.
At this point, the integration does not exist yet, it needs a valid
configuration.
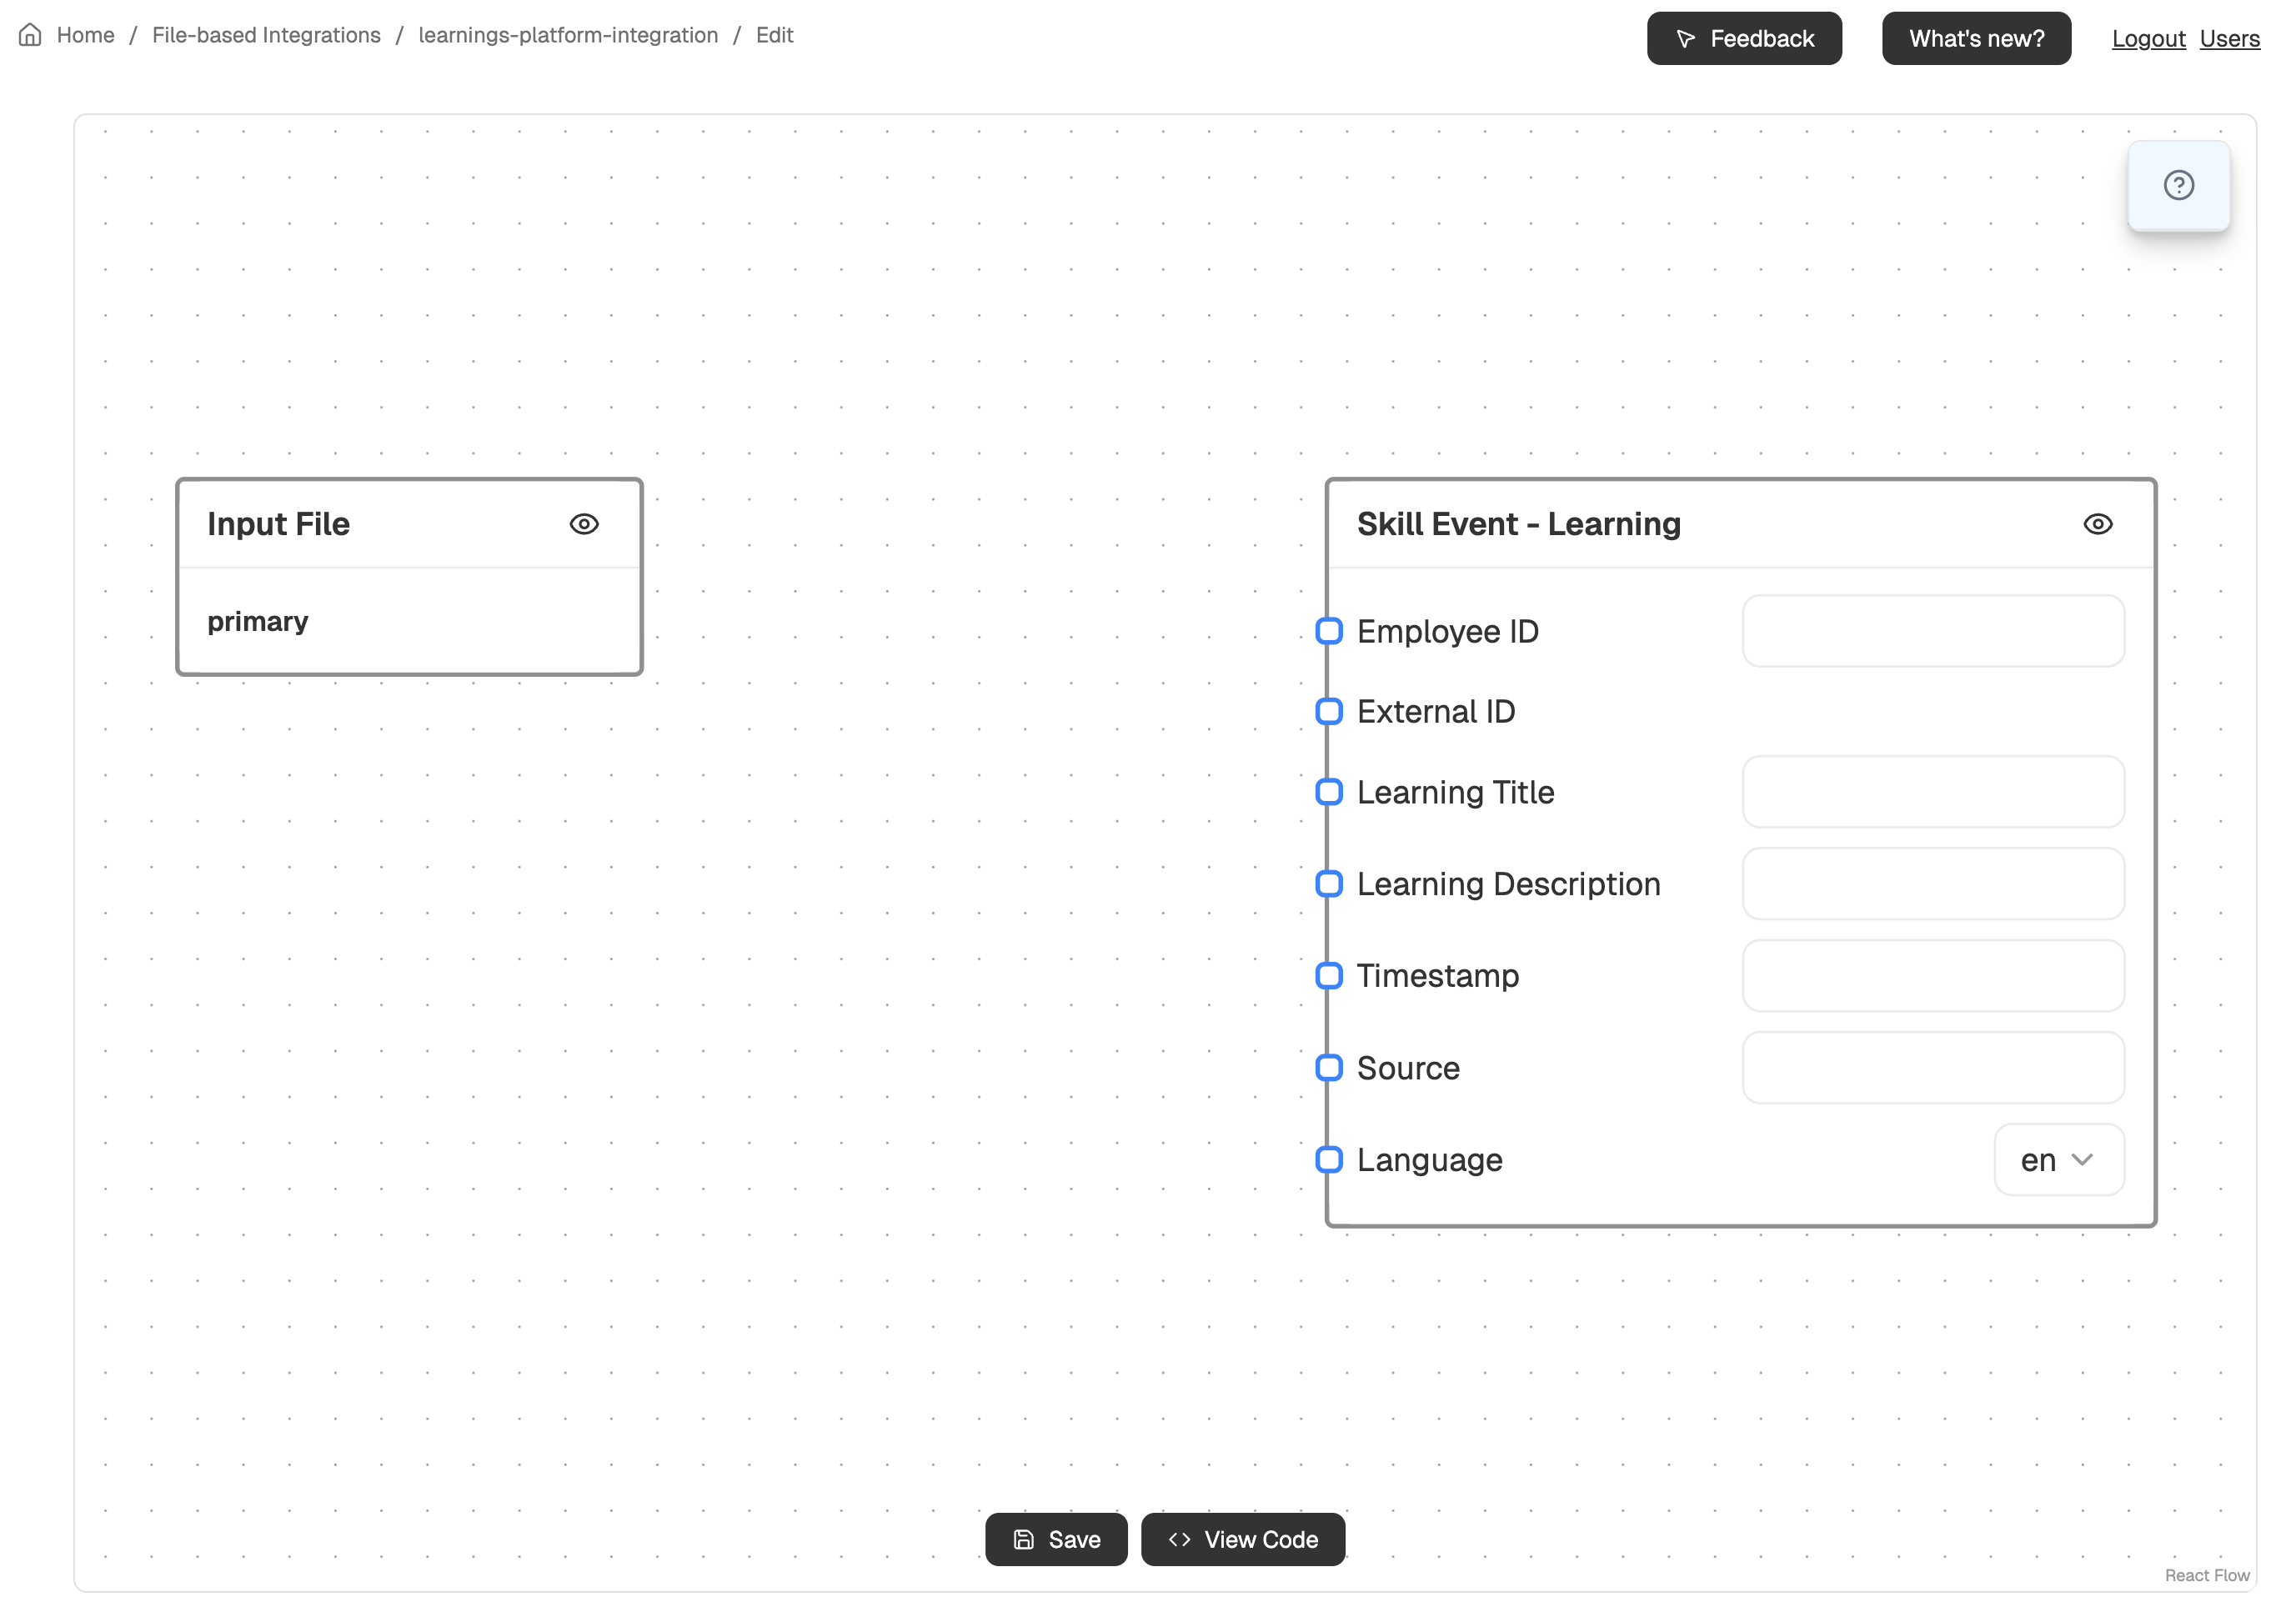
Step 2: Configuring the input node
The input node is the first node in the integration. It is used to configure the input data for the integration, which includes all inputs (files or connections) needed to load the datasource into the SkillEngine API. At first, the input node will be empty, only showing aprimary tag. That bold
tag indicates the “alias” of the input. It is intended to help you differentiate
between the different inputs you have configured.
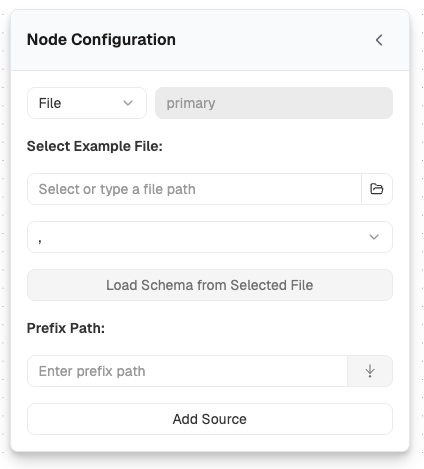
Configuring the primary input
The primary input is pre-created with the aliasprimary. This alias is just a
label to help you tell inputs apart — it does not affect the data source.
There are multiple possible source configurations:
- Setting up files as a source:
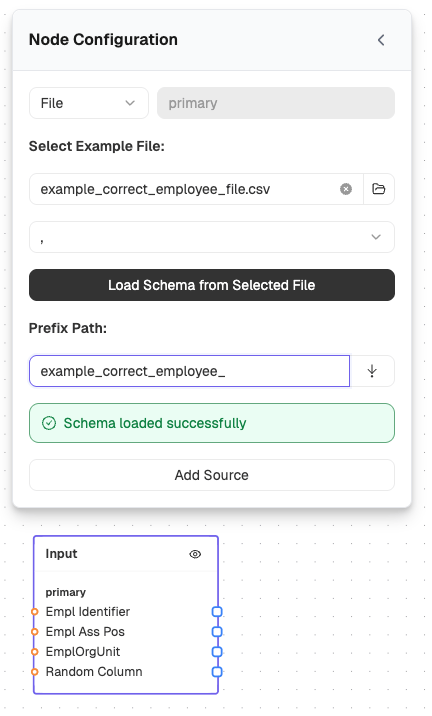
- Example file: Select an example file from S3 using the file picker. This helps the Data Integrator understand the column structure of your data. It is also used for previewing data later.
- Load Schema from Selected File: After selecting an example file, click this button. The Data Integrator reads the column headers and populates the input node with output handles — one per column. These handles are what you connect to operations and the output node later.
- Prefix: Configure the prefix that identifies which uploaded files belong
to this input configuration. When a file is uploaded to S3, the Data Integrator
matches it to an integration based on this prefix (the first part of the file
name). For example, a prefix of
learning_eventswould matchlearning_events_20260101.csv. - Separator: Choose the CSV separator — either
,(comma) or;(semicolon). This must match the actual delimiter used in your data.
- Setting up a connector as a source:
- Connector: Select a connector or create a new one.
- Load Schema: This happens automatically when you select a connector.
- Note that preview is not yet possible for connectors.
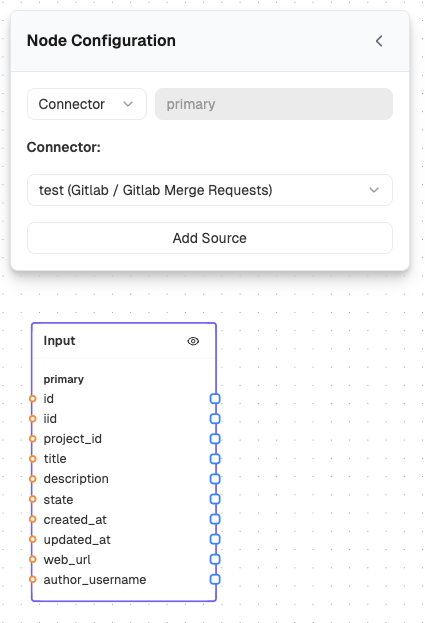
Adding extra sources (optional)
If your integration needs data from multiple sources (e.g., a mapping file in addition to the main data source):- Click Add Source at the bottom of the input node detail panel.
- Choose a sensible alias for the new source (e.g.,
identity_mapping), indicating what it contains. - Configure the new source the same way as the primary input: select an example file, load the schema, set the prefix and separator.
- The primary input is special: uploading a file that matches the primary prefix triggers the integration (if enabled). Extra inputs do not trigger runs — the integration always uses the latest version of each extra input.
Step 3: Joining configured inputs
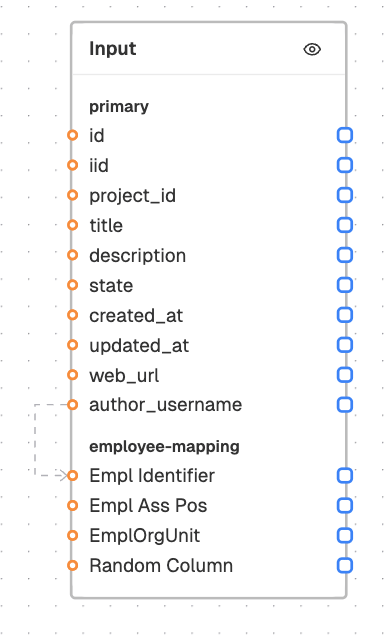
If you added extra sources in the previous step, you need to define how they join to the primary input (or to each other).- On the left side of the input node, each input’s columns appear as connection handles.
- Drag an edge from a column in one input to a column in another input to
define a join key. For example, drag from
primary.employee_idtoidentity_mapping.source_id. - Join arrows can only go downwards (from an input listed higher to an input listed lower). The primary input is always at the top.
- All joins are left outer joins — rows from the upper input are preserved even if there is no match in the lower input.
- You can join on multiple columns between the same two inputs by adding multiple join edges.
Join edges appear as dotted lines on the canvas to distinguish them from
regular data flow edges.
Step 4: Configuring the output node
The output node defines how the transformed data maps to the SkillEngine API. Click the output node to open its detail panel.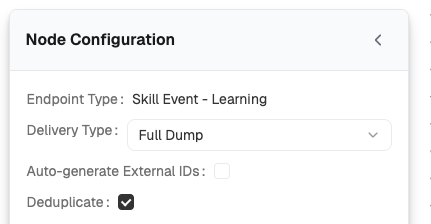
Delivery Type
- Full Dump: Every run replaces the entire dataset. The Data Integrator compares the new data with the current API state and creates, updates, or deletes entities as needed to make the API match the data.
- Delta (diff): The integration tracks changes incrementally. Useful when your source data contains explicit create/update/delete indicators or when your dataset is large.
Auto-generate External IDs
- For certain Entity Types, you can toggle Auto-generate External IDs. When enabled, the Data Integrator generates a unique identifier by hashing the values of the fields you connect to the output node. This is useful when your source data does not have a natural unique key.
Step 5: Adding operations to transform data
Operations are intermediate nodes that transform data between the input and output nodes. They are added via the right-click context menu on the canvas. Right-click on an empty area of the canvas to see the list of available operations. Each operation is a self-contained transformation with its own input(s) and output(s).Available operations
Value Mapping
Value Mapping
Maps source values to target values. Useful for converting codes or categories
from the source system to values expected by the SkillEngine API.
- Input: A single field (connected from the input node or another operation).
- Output: The mapped value.
- Configure key-value pairs in the detail panel: each row maps a source value (left) to a target value (right).
- Optionally set a default value — used when the source value does not match any of the configured mappings. If no default is set, unmatched values pass through as-is.
Date Parser
Date Parser
Parses date strings from the source data into a standardised format.
- Input: A single date field.
- Output: The parsed date in ISO format.
- Configure the date format using
strftime directives
(e.g.,
%Y-%m-%dfor2026-01-15,%d/%m/%Yfor15/01/2026).
String Concat
String Concat
Concatenates multiple input fields into a single output string.
- Inputs: Two or more fields, can be a literal value (by leaving it unconnected).
- Output: The concatenated string.
- Configure a separator (e.g.,
-,,, - Null values are ignored during concatenation.
aandnullwill becomea;aandbwill becomea-b. The separator is ommitted on null values.
Slugify
Slugify
Converts text to a URL-safe slug format (lowercase, special characters replaced
with hyphens).
- Input: A single text field.
- Output: The slugified text.
Filter
Filter
Filters rows based on one or more conditions. Rows that do not match are
excluded from further processing.
- Input: A single field to evaluate.
- Output: The same field, but only for rows that pass the filter.
- Add one or more conditions in the detail panel:
- Comparison:
equals(=) ornot equals(!=). - Value: The value to compare against.
- Logical operator: Combine multiple conditions with
ANDorOR. Operations get added in order of appearance. So,filter_1,ORfilter_2,ANDfilter_3will be evaluated as(((filter_1) OR filter_2) AND filter_3).
- Comparison:
Coalesce
Coalesce
Returns the first non-null/non-empty value from multiple inputs. Useful
when a value could come from different source columns and you want to pick the
first available one, e.g. dates.
- Inputs: Fields in order of fallback.
- Output: The first non-null value from the inputs, evaluated in order of appearance.
Custom Properties Output
Custom Properties Output
A specialised output node variant for mapping data to Custom Properties on the
SkillEngine API. Use this instead of the regular output node when your
integration needs to set Custom Properties.
- Maps input fields to Custom Property names.
- Produces a JSON-encoded structure for each Custom Property.
There is a list variant of Custom Properties Output, which is used to
set list[text] Custom Properties. This node aggregates multiple rows of your
data into a single list value. You need exactly one Custom Property List
integration per list[text] custom property.
Step 6: Connecting nodes
Edges are the lines that carry data from one node to another. They define the data flow of your integration.How to connect nodes
- Each node has handles: small connection points on its edges.
- Right-side handles (source/output): Data flows out of the node.
- Left-side handles (target/input): Data flows into the node.
- Drag from a right-side handle to a left-side handle on another node to create an edge.
- Handles are labelled with the field name (e.g.,
primary.email,mapped_value,external_id). - You can connect input node columns directly to output node fields (for pass-through mapping) or route them through one or more operations first.
Tips
- You can multi-select nodes by holding
Shiftand clicking. - Copy/paste nodes with
Ctrl+C/Ctrl+V(orCmdon macOS). - Use the Preview button (eye icon) on a node to see a sample of its output data before saving.
Step 7: Previewing and saving
Preview
- Click the Preview button (eye icon) on a node to see a sample of its output data before saving.
- This is a dry run of the first 50 rows of the integration, it does not actually send any data to the SkillEngine API.
- Connector outputs and some nodes do not support preview.
Save
- Click the Save button at the bottom of the editor to persist your integration configuration.
- If this is a new integration, saving creates the integration for the first time. It does not exist until you save.
- The integration is saved but not automatically enabled. You need to enable it separately (see below).
Step 8: Enabling the integration
After saving, navigate to the integration details page.- The details page shows metadata about the integration: Integration Name, Entity Type, Delivery Type, and Enabled status.
- Use the toggle switch to enable or disable the integration.
- When enabled, uploading a file matching the primary input’s prefix will automatically trigger a run, or on a schedule for a connector primary input.
What’s next?
Once your integration is set up and enabled, see How to run an integration for details on triggering runs, monitoring progress, and reviewing results.FAQ
When should I use Auto-generate External IDs?
When should I use Auto-generate External IDs?
Auto-generate External IDs is a last resort for when your source data does
not provide any stable, unique identifier for each record.Why you should avoid it when possible:External IDs are generated by hashing a combination of fields from the input
data — typically all fields except highly variable ones like timestamps. This
means:
- If any of the hashed fields change (e.g., a company name is corrected), the generated ID changes. The Data Integrator cannot tell whether this is an update to an existing record or a brand new record.
- This leads to duplicate data in the API, missed deletes, or unexpected overwrites.
- Legacy systems that genuinely have no reference ID for records.
- Text-based data sources with no natural key.
What does the Deduplication option do?
What does the Deduplication option do?
The Deduplication option removes duplicate rows from your input data before it
is loaded into the API. When enabled, it keeps only the first row in a set
of rows that share the same external ID.
We recommend enabling deduplication for all integrations. It is enabled by
default.
When should I use Delta delivery instead of Full Dump?
When should I use Delta delivery instead of Full Dump?
Choose Delta delivery when your source system cannot or should not export
all data every time. This is common for:
- Large datasets like learning histories, where re-exporting everything on each run is impractical.
- Systems that only track changes — the source only knows about new, changed, or removed records since the last export.
operation field on the output node. The operation
value for each row is either:update— creates the entity if it does not exist, or updates it if it does.delete— removes the entity from the API.
What if my file format changes?
What if my file format changes?
If the content stays the same (still the same entity type) but the column
structure changes — for example, columns are renamed, added, or removed — you
need to update your integration configuration:
- Open the integration in the editor.
- On the input node, select a new example file that reflects the updated format.
- Click Load Schema from Selected File to update the column handles.
- Reconnect any broken or new edges between the input node and your operations or output node.
- Save the integration.
How do I load resumes from PDF files?
How do I load resumes from PDF files?
Resumes can be loaded with the document content in the input file (connect it to
Base64 Content), or from PDF files that the input file references by path.
This section covers the second option: the PDF files, plus an index file with one
row per resume that holds the Employee ID and the path of the PDF. The file
layout is described in the
Employees specification.
- Create an integration with Integration Type Skill Event - Resume Document.
- Set the primary input to the index file.
- On the output node:
- Connect the Employee ID column to the Employee External ID.
- Connect the path column to PDF Path (relative to input folder).
- Set the MIME type to
application/pdf. - Connect the
external_idcolumn if your index file has one. Otherwise, enable Auto-generate External IDs: this gives one resume per Employee. Keep the Source a fixed value, because it is part of the generated ID.
- Save and enable the integration.